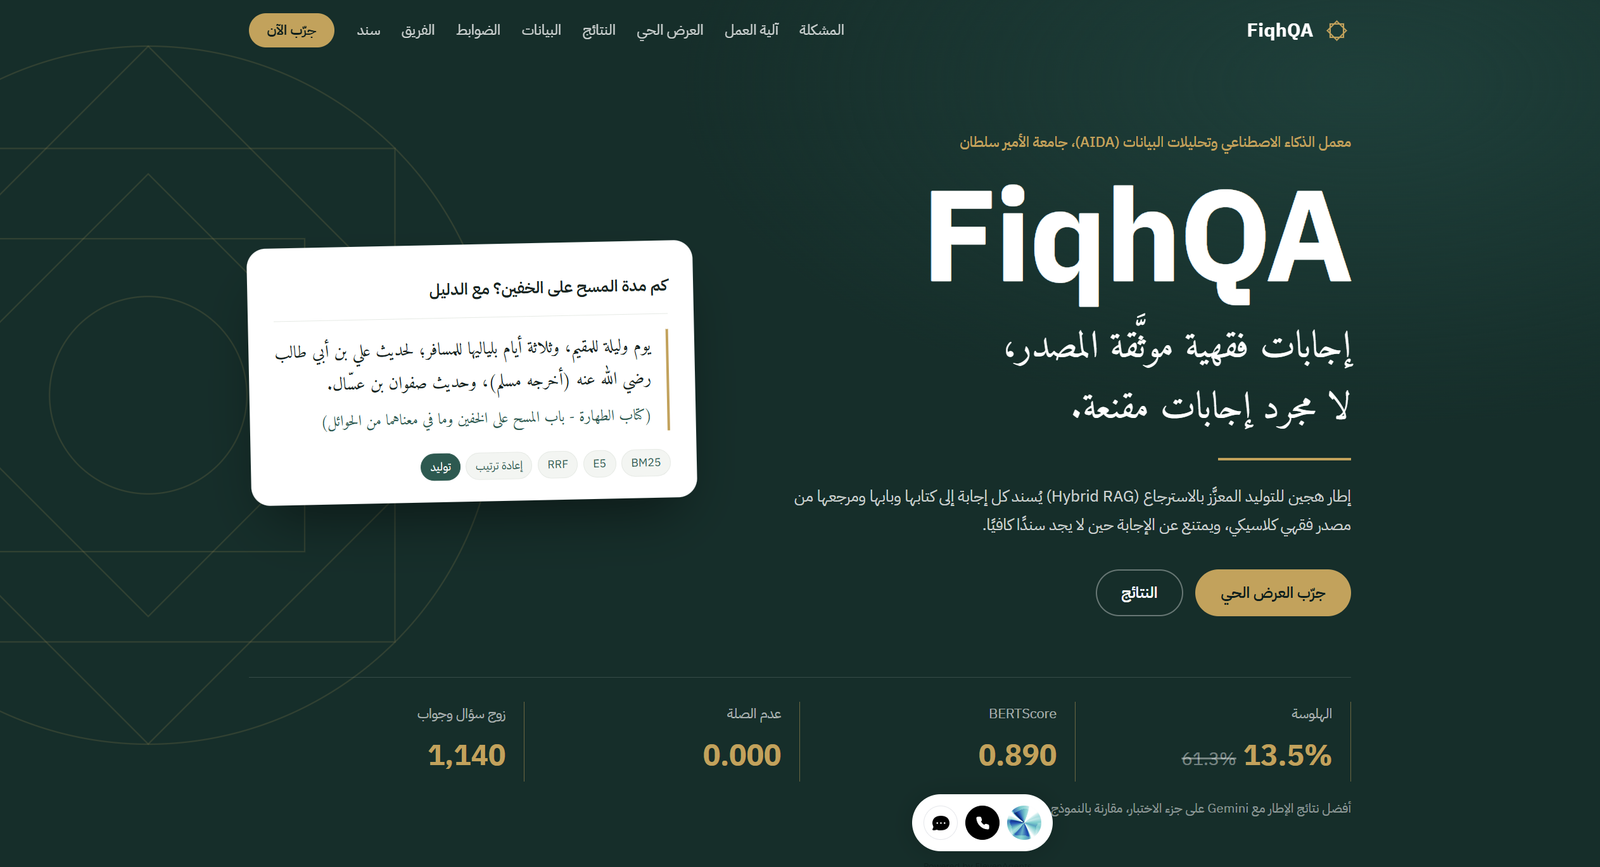
Large language models alone are not enough for questions of Islamic jurisprudence. They can produce rulings that sound convincing but have no basis in the sources, give no way to trace where an answer came from, and drift beyond the question asked. Answering without retrieval, Gemini 2.5 Flash hallucinated in 61.3% of cases.
FiqhQA addresses this with a new dataset built from a classical fiqh book and a hybrid retrieval pipeline. Each question is matched with BM25 keyword search and multilingual E5 semantic embeddings, the two rankings are merged with Reciprocal Rank Fusion (RRF), and the top passages are reranked by an Arabic cross-encoder. The model then answers in Modern Standard Arabic from the retrieved text only, citing the book and reference — and declines to answer when nothing relevant is retrieved.
Key features
- 1,140 Q&A pairs from a classical fiqh book
- Hybrid retrieval: BM25 + multilingual E5
- RRF fusion & Arabic cross-encoder reranking
- Book and reference cited in every answer
- Abstains when retrieval finds no support
- Evaluated on two LLMs and seven metrics
Results
Compared with the model alone and a standard RAG baseline, FiqhQA-RAG improved results for both Gemini 2.5 Flash and SILMA-9B-Instruct. With Gemini, hallucination fell from 61.3% to 13.5%, completeness rose from 0.426 to 0.888, BERTScore reached 0.890, and irrelevance dropped to zero.